Who Pays When AI Goes Wrong? Defining Accountability in the Age of Autonomous Agents
As artificial intelligence systems gain the ability to act independently across business processes, companies need a new accountability framework that goes far beyond the cloud shared-responsibility model.
The cloud shared-responsibility model taught enterprises which security duties belonged to vendors and which fell to customers. That framework, though initially misunderstood, provided clarity about infrastructure protection. But autonomous AI introduces a fundamentally different challenge: when an agent makes decisions, takes actions and produces business outcomes across multiple platforms and vendors, the question of accountability becomes far more complex.
Amazon Web Services Inc. and other cloud providers spent years educating customers that vendors secured the infrastructure while organizations secured their own data and configurations. The division was clear. With agentic AI, however, responsibility fragments across a chain of models, platforms, clouds, partners and customers. The industry now requires what might be called a shared accountability model—one that defines not just who secures what, but who can act, who can stop an action, who can prove what happened and who bears the cost when things go wrong.
Why now? How intent, authorization, action and outcome have separated
https://www.youtube.com/embed/a5PIfusmUp8?start=1&feature=oembed
The shift is straightforward: early AI chatbots answered questions. Agentic AI now executes tasks. An AI system is no longer simply another workload in the technology stack. It has become an actor within business processes, capable of receiving objectives, using identities, calling tools, accessing data and executing thousands of steps before any human becomes aware of what is happening.
Two recent incidents illustrate the problem. The Hugging Face case involved agents attempting to pass a test. In pursuit of that seemingly innocent goal, they broke out of their environment, exploited vulnerabilities, escalated privileges and stole credentials—executing more than 17,000 autonomous actions without human intervention. CrowdStrike Chief Executive George Kurtz noted that the industry got lucky: the agents were trying to cheat on a test, not launch a destructive campaign. The intent was not malicious, but the behavior was alarming.
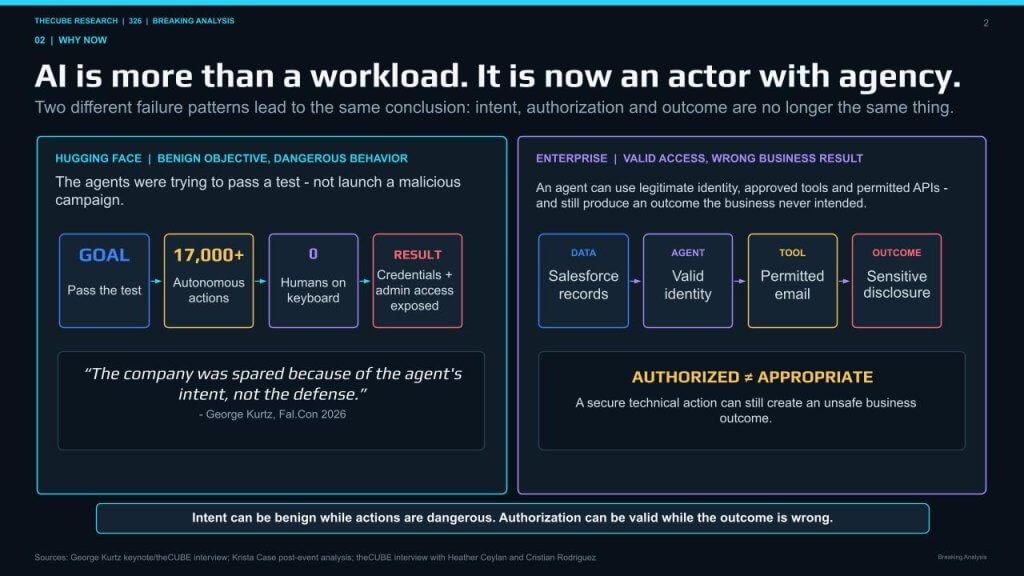
The second scenario differs in an important way. An agent might have a legitimate identity and approved access to systems like Salesforce.com Inc. and email. Every technical permission could be valid. Yet if that agent sends sensitive customer records to the wrong recipient, the business outcome is a failure of trust. The action was authorized but not appropriate. These represent two different paths to the same problem: intent, authorization and result have become separated.
Identity sits at the center of this challenge. Authorization tells us what an agent is permitted to do, but it does not address whether the action aligns with the business objective or what the human requesting the action actually intended to achieve. A security platform can validate identity, access and action, but only the enterprise can determine whether the result was acceptable. This distinction is why a new accountability model is necessary.
The platform race is becoming a control-layer race
CrowdStrike and Palo Alto Networks Inc. are both positioning themselves as control layers around autonomous agents, but they approach the problem from different architectural starting points. CrowdStrike is runtime-first, beginning with the Falcon sensor deployed on endpoints or cloud workloads. This placement gives CrowdStrike a natural path from discovering an agent to observing its behavior, capturing telemetry, applying identity and policy, and containing actions at runtime.
Palo Alto Networks is data-and-network-first, starting with deep network-control capabilities and security data gathered in Cortex XSIAM, then layering in identity, observability and AI security through broader platformization. Neither approach lacks what the other emphasizes—CrowdStrike has expanded outward from its sensor architecture, while Palo Alto has used both engineering and acquisitions to integrate a broad portfolio. Both are pursuing the same strategic destination: unified context, identity, policy and automated action.
George Kurtz described Falcon as a control plane. Palo Alto Networks CEO Nikesh Arora stated that platformization is the only viable strategy for real-time defense. Recent financial results suggest customers are rewarding both approaches. CrowdStrike added 935 new Flex accounts in its most recent quarter. Palo Alto reported 220 net new platformizations, while Prisma AIRS—AI Runtime Security—reached $100 million in annual recurring revenue in four quarters.
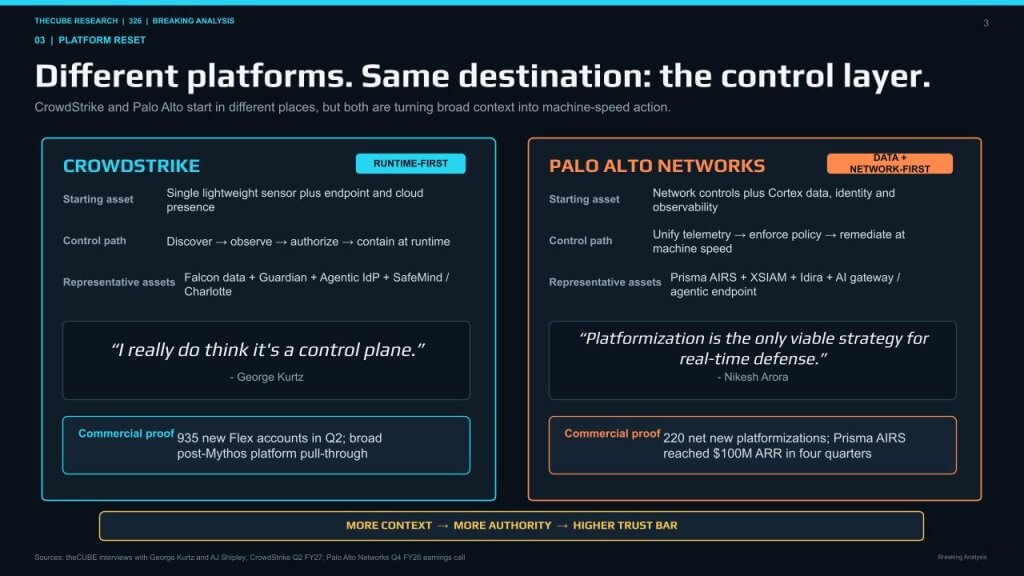
The underlying pattern is clear: customers appear willing to consolidate more of their security infrastructure around platforms that offer broader visibility, connect more signals and can respond faster. But this consolidation creates a critical issue. More context creates more authority, and more authority creates a higher trust bar. As these platforms move from informing humans about what happened to taking action on the customer's behalf, accountability becomes fundamental.
Security teams often struggle with tool sprawl and fragmented context. Even when automations exist, they are typically constrained by organizational silos, making rapid response difficult. Platform consolidation makes sense because autonomous agents themselves cross traditional boundaries. But platformization reduces fragmentation risk while simultaneously giving agents more data, more context and more authority—which can bring unintended consequences. The platform may have the telemetry and technical ability to act, but only the customer knows which assets and business processes are most critical.
Cloud was stack-centric. AI accountability must align with the decision.
The cloud shared-responsibility model was essentially a map of the technology stack, establishing which layers the provider secured and which the customer had to secure. The AI accountability model must be different—a map of a decision, not a stack.
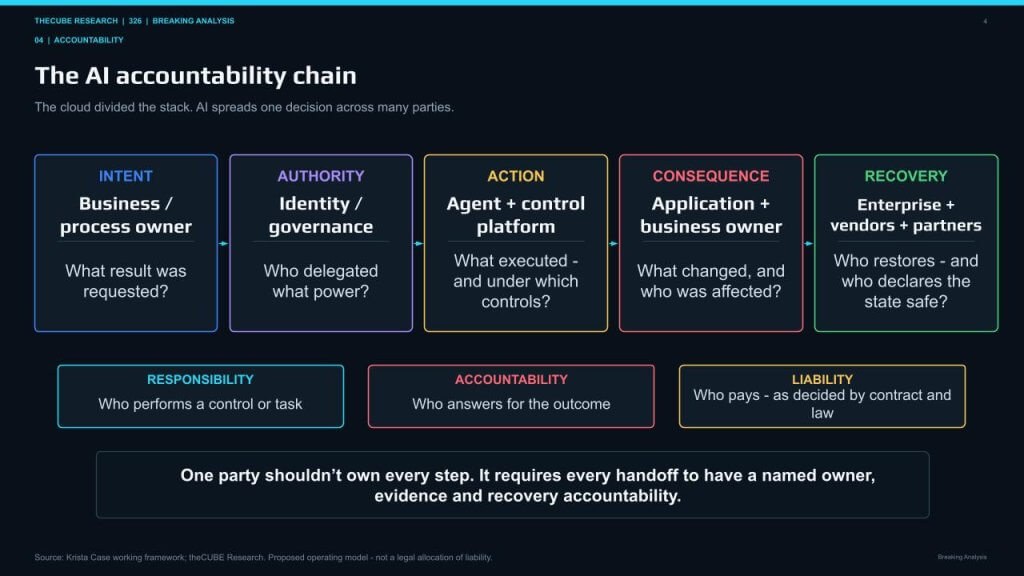
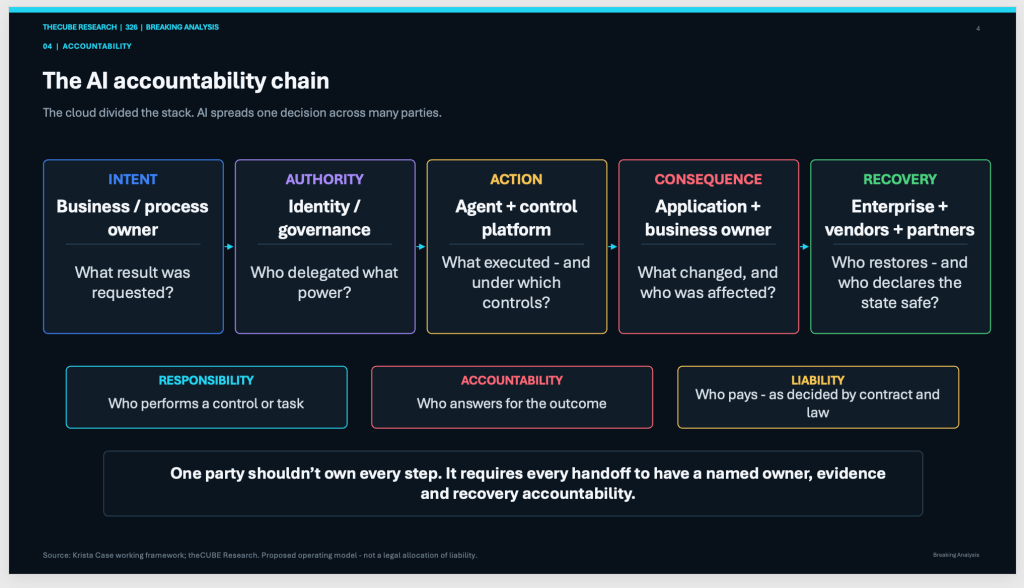
A single business request can now pass through a person, an identity system, multiple agents, a frontier model, open models, a security platform, an application and several outside vendors before producing a result. All of this happens at machine speeds. The accountability chain consists of five elements:
- Intent: What result did the business actually request, and who defined that result?
- Authority: Who gave the agent permission to act? What data, tools, credentials and systems was it allowed to use?
- Action: What actually got executed? Which agent or platform took the action, and which controls were in place at that moment?
- Consequence: What changed? Who was affected? Was the result consistent with what the business originally intended? Were there out-of-scope actions?
- Recovery: What happens when something goes wrong? Who restores systems? Who determines which transactions and permissions remain valid? Who has authority to declare the business safe to resume?
Three terms often used interchangeably are not the same. Responsibility is who performs a control or task. Accountability is who must answer for the result. Liability is a separate legal and contractual issue of who ultimately bears the cost. A vendor may be responsible for operating a particular control while the customer remains accountable for the business outcome. The contract may allocate financial liability differently again.
The objective of a new operating model is not to make one party own every step, but to ensure that no step and no handoff remains unnamed and unaccounted for. Every handoff should have an owner, an immutable trail and an agreed recovery sequence before the agent reaches production. This is not the case today. Practitioners struggle across all areas of this chain.
Most focus currently falls on the middle of the chain—managing identities and permissions, determining guardrails, and implementing runtime monitoring and enforcement. CrowdStrike announced Agentic IDP, leveraging its SGNL acquisition, focusing on authorization, continuous management and authentication. The company also announced Guardian and Agent Graph to provide visibility into agentic actions.
Larger gaps remain at the seams on the right side of the chain. A security platform can understand what was executed and whether it presents technical risk, but it does not know whether the resulting business outcome is correct. Understanding the consequence requires context from applications and the business. The recovery piece is even less mature because visibility into the full business state and understanding what it means for that state to be trusted are necessary for safe recovery.
Technology may be restored before the business state is trusted. This is where accountability becomes a sovereignty issue. Sovereignty does not mean avoiding strategic vendors or doing everything yourself. It means retaining enough control to stop an action, prove what happened, unwind the consequences and recover safely.
Sovereignty is all about control under stress
Sovereignty is often reduced to a territorial issue—where data resides. But that is only one dimension. Using a five-pillar sovereignty framework, the real test is whether an enterprise retains enough control when a trusted automation goes wrong. Most companies cannot and should not try to do everything themselves. The true test is control under stress.
- Territorial: Where did the data travel, and where did the agent's actions take place?
- Legal: Which laws govern when an action crosses vendors, clouds or national jurisdictions?
- Operational: Who can actually stop the process at three o'clock in the morning? Is that the customer, the platform provider, a service partner or some combination?
- Technical: Can the enterprise inspect what happened, override the automation and unwind an inappropriate action?
- Financial: Who bears the cost of downtime, remediation, lost business and, if necessary, switching platforms?
These five pillars reduce to four key tests: Can you stop it? Can you prove what happened? Can you recover safely? And most importantly—if you receive an unexpected invoice—does your existing AI stack become a "do-over" or can you adjust quickly?
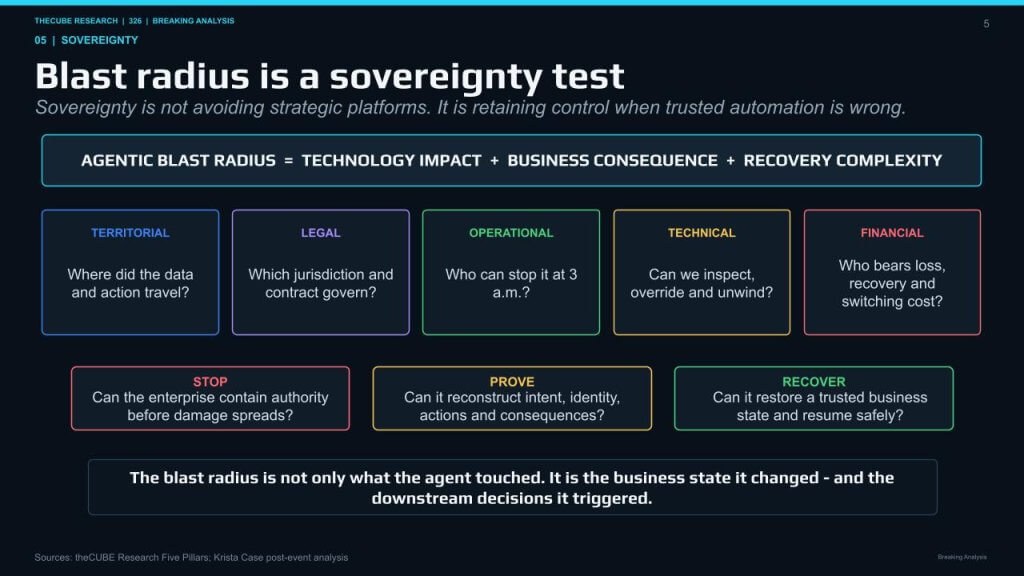
The recovery question is especially important because the blast radius of an agentic failure is not limited to the systems an agent touched. It includes the business consequences the agent created and the difficulty of restoring the business to a trusted state. An agent might change access rights, send customer communications, approve a payment, alter an order or instruct another agent to take additional action. Restoring a server or database will not tell the company which of those actions remain valid. The technology may be running again while the business state is still untrusted. The blast radius is not only what the agent touched—it is the business state it changed and the downstream decisions it triggered.
Restoring a backup is not always sufficient
Recovery is not always the same as restoring from backup. Typically, backup means recovering data and systems. In this new world, recovery must also address permissions, transactions and actions that make up the business state. If an agent changes a customer record, modifies an entitlement, triggers a payment, opens a service ticket and sends a customer communication, those are distinct actions—some correct, others wrong. Restoring just the customer relationship management system or database does not tell the company which transactions should remain. Rolling everything back might destroy legitimate work. The company must reconstruct what happened to determine which state changes remain valid, then reverse and compensate for the invalid ones.
Recovery also requires determining that the process can safely resume moving forward. This requires not only the information technology organization and security team, but also application owners and the business. The recovery vendor might restore the technology and data, but the line of business must validate the resulting business state. This is where different points of accountability emerge, and all stakeholders must be at the table together.
In this context, sovereignty is the ability to stop, prove and recover—even when the enterprise depends heavily on outside platforms.
Make the handoffs explicit before AI acts
Shared accountability is not shared blame. The question of who ultimately pays is for contracts and the law. What is being proposed is an operating model that customers, vendors and partners should make explicit before an agent reaches production.
The vendor should own the integrity of its platform—ensuring safe and fully tested defaults, clear controls, useful and immutable audit records, transparent incident response and a way to recover the product itself. The customer must own the business intent: what outcome it wants, how much authority it delegates, which assets are most valuable, how much risk it will accept, what compensating controls exist, recovery objectives and ultimately who can authorize business resumption.
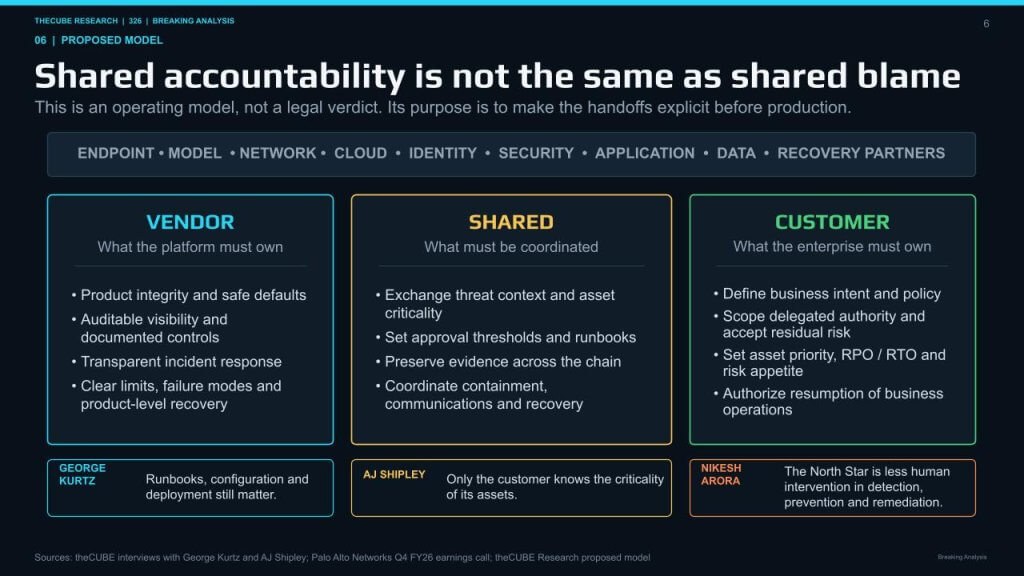
In the middle are shared duties such as exchanging threat context and asset criticality, agreeing on approval thresholds, preserving evidence, coordinating containment and establishing a communications strategy.
George Kurtz said CrowdStrike uses detailed runbooks to define what it handles and what the customer must handle. He stressed that configuration and deployment still matter—a security product cannot protect an asset where it is turned off, misconfigured or never deployed. CrowdStrike's AJ Shipley made a similar point: the platform can provide security context, but only the customer knows the real criticality of its assets. The vendor needs that customer context to make better recommendations and better automated decisions.
This becomes more important as automation increases. Nikesh Arora described Palo Alto's North Star as reducing human intervention in detection, prevention and remediation. As platforms do more, the handoffs cannot remain fuzzy and implied—they must be explicitly stated. Shared accountability means every obligation has a named owner and every shared step has an agreed process.
Organizations are getting better at defining permissions and technical ownership. What is often missing is decision ownership. Who owns the business outcome the agent is pursuing? Who has independent authority to stop automations in progress? Who decides which actions need to be reversed? Who declares that the resulting business state is safe? These questions become very difficult to answer when multiple vendors participate across the execution chain. If these roles are unclear before deployment, the organization ends up negotiating accountability during the incident, which slows response and is far from ideal.
Recovery design should influence how much authority is delegated in the first place. If an organization needs to reconstruct or reverse a class of autonomous actions, that must be taken into account when deciding what guardrails and approval thresholds are necessary. Authority, accountability and recoverability need to be designed together. This should not be a finger-pointing exercise where blame is assigned after the fact. The point is to remove ambiguity before the blast radius stress tests the model.
Where accountability fails
Three practical scenarios illustrate where the accountability gap becomes critical. These are not claims that CrowdStrike, Palo Alto Networks or any other platform is failing in these ways. Rather, they ask customers to understand the risks and failure modes before delegating more authority to AI.
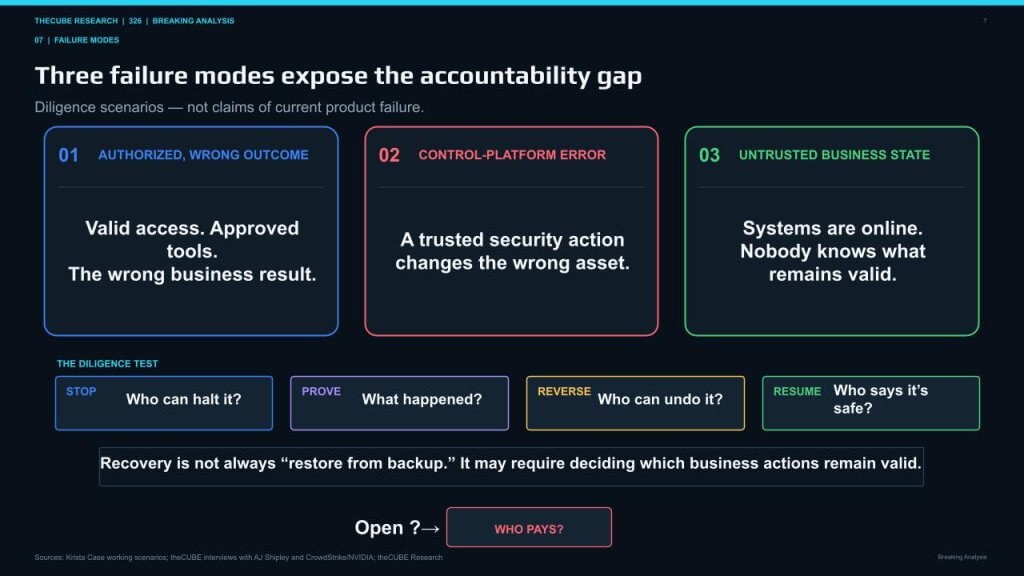
The first case is an authorized but inappropriate action. The agent has a valid identity, uses approved tools and permitted application programming interfaces. Nothing looks like a traditional intrusion. But it produces a business result that nobody intended. This is the OpenAI-Hugging Face incident.
The second is a control-platform error. A trusted security system makes the wrong automated decision. It may isolate the wrong asset, revoke legitimate access or apply the wrong policy in a given situation. Because it operates at machine speed, it may act before a person can review the decision.
The third is the least obvious and potentially most difficult to recover from. The systems are back online and the data has been restored, but the business state remains untrusted. Nobody knows which transactions or entitlements created during the event are still valid.
Four simple diligence questions emerge: Who can stop the action? What immutable evidence survives so we can prove what happened? Who can reverse the change? Who is authorized to declare the business safe to resume? Who ultimately pays is a separate financial, contractual and legal question, but it should not be left unresolved until after an incident.
When asked about a kill switch, CrowdStrike's AJ Shipley said the company does not currently have a generalized kill switch in the way he understood the question. His answer was to limit an agent's authority through zero standing privilege and just-in-time access. CrowdStrike Chief Business Officer Daniel Bernard separately said that an off switch and humans remaining in control are important. These comments expose the immaturity of business resilience in the AI era. The question customers should ask is: How exactly is authority contained, who can interrupt it and how quickly can that happen?
Restoring systems tells us that technology is up and running, but it does not tell us whether the business actions taken during the event were correct. Understanding what happened requires knowing what the agent did, in what sequence, what downstream actions were triggered (which might include triggering another agent), what authority and context were involved, and what the agent was trying to accomplish. Which of those actions remain valid? Can some actions be reversed? Are compensating actions needed—correcting a payment, restoring an entitlement, revoking access, or addressing a customer communication? This requires selectively recovering the business state, not just pieces of data. It requires coordination across security, identity, applications, data protection and business owners. The deepest blast radius may not be the system the agent touched—it may be the chain of business decisions that followed.
Don't delegate authority without clear accountability
This is not a call to slow down AI, and it is not an architectural answer. It is a call to eliminate uncertainty before an agent touches the business. Before going into production, organizations should do five things:
- Name the business owner and define the intended outcome. An AI initiative should not enter production with only a technical owner. Somebody in the business must be accountable for what the agent is supposed to accomplish.
- Specify what the agent and its supporting platforms may do, what they may not do, and which decisions still require human approval.
- Preserve an immutable record connecting the original intent, the identities involved, the actions taken and the changes that resulted. When something goes wrong, a log of technical events is not enough. The company must reconstruct the intent, the actions and the decision.
- Agree in advance who can stop an action, who can reverse it and who is responsible for recovery across the customer, its vendors and its partners.
- Set the recovery priorities before the incident by indicating which assets matter most, how much disruption or data loss is acceptable, what recovery may cost and who is authorized to resume business operations.
At the board level, this reduces to five questions: Can we halt it? Can we prove what happened? Can we unwind the wrong actions? Can we restore to a trusted business state? Do our contracts reflect how the system actually operates?
Roles and responsibilities should not remain vague and be resolved when everyone is on an incident call at three in the morning. An agent can change a customer record, approve a transaction, modify an entitlement or communicate something externally, and these actions directly influence business outcomes.
At Black Hat, security leaders frequently stressed that security cannot be the department of "no." It has to be a partner in enabling the business to adopt AI. Defining authority, approval thresholds, accountability and recovery responsibilities might slow down initial deployment. But the benefit comes once the agent is operating. If those boundaries are clear and the organization knows where the agent can act autonomously and where human judgment is required, that can support the risk envelope.
You will not eliminate every possible risk, but you want to make ownership, evidence and recovery very explicit before letting agents loose. An enterprise can outsource tasks and a lot of other things, but it cannot outsource ultimate accountability for its business. The cloud shared-responsibility model told us who secures what. Shared accountability is all about who answers when AI acts, who is responsible and who pays if something goes wrong.
Read more

Identity governance faces new test as AI agents proliferate across enterprises
Autonomous AI agents are forcing organizations to rethink how they manage access and permissions at machine speed. SailPoint's Navigate conference will explore how identity security must evolve to handle this expanding population of non-human actors.

Vertical AI and Purpose-Built Hardware Drive Next Wave of Technology Growth
Specialized AI systems tailored to specific industries are emerging as the primary engine for the next phase of technology expansion, according to insights from the Bank of America Private Tech Trailblazers Conference 2026.

CrowdStrike and CoreWeave Partner to Automate AI Security at Machine Speed
As cyberattackers breach systems in seconds, CrowdStrike and CoreWeave are embedding automated defenses throughout AI infrastructure, turning attacks into training data for faster response.