Reflection AI Opens Beam Model Weights, Releases Optimization Recipes for Developers
The startup has published its 500-billion-parameter language model on Hugging Face alongside technical resources for customization, including training recipes and inference optimization tools.
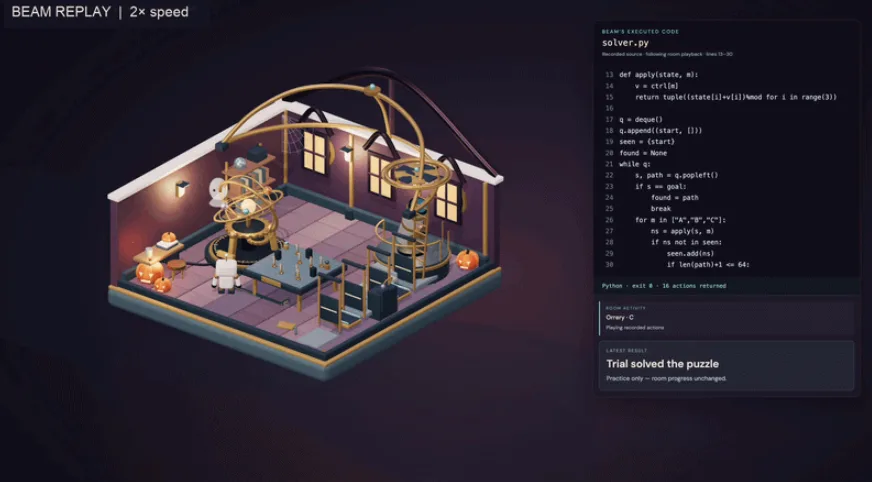
Reflection AI Inc. has made Beam's model weights publicly available through Hugging Face, marking the open-source release of its inaugural large language model. The startup simultaneously unveiled technical resources designed to help developers adapt and refine the algorithm for their own applications.
Introduced the previous week, Beam stands among the most capable open-source language models available today. The model contains approximately 500 billion parameters but delivers performance comparable to models that are four times larger on certain benchmarks, while consuming substantially less computational resources and memory.
Training at Scale with Custom Reliability Systems
Reflection AI spent two months training Beam using thousands of high-end graphics processing units. Large-scale training operations of this magnitude frequently encounter errors that can degrade model quality. The company addressed this challenge by engineering custom reliability optimization algorithms to maintain training integrity.
The reliability work focused heavily on preventing training-inference mismatches, which occur when slight configuration differences appear between components in the training environment. Reflection also built an automated system capable of correcting certain data quality issues by reverting training runs to earlier checkpoints rather than restarting from the beginning. According to the company, these optimizations allowed Beam to be trained with virtually zero cluster downtime.
Multiple Model Versions and Customization Tools
The released weights come in several formats, including a standard version and quantized variants that store information in smaller data units. Quantization reduces output quality somewhat in exchange for improved hardware efficiency.
Alongside the weights, Reflection AI provided training recipes—code templates that allow users to fine-tune Beam for specific purposes. A developer working on programming tools, for instance, could use these recipes to enhance the model's coding abilities. The company also included measurement tools to help developers evaluate how their customizations affect Beam's capabilities and safety features.
Inference Optimization and Serving Infrastructure
Reflection AI released a drafter model designed to enable speculative decoding, an inference technique that reduces hardware demands. The approach uses the lightweight drafter model to generate an initial response, which Beam then validates before presenting to the user.
Running inference efficiently typically requires a software serving engine, and adapting language models to specific engines can demand considerable engineering effort. Today's release includes pre-configured Beam setups for several widely-used serving engines. Developers also gain access to fused kernels—code snippets that combine multiple inference operations into single calculations to accelerate processing.
Upcoming Releases and Community Contributions
Reflection AI intends to release additional training recipes in the coming days that will enable Beam to improve its own output quality through self-distillation. The company also plans to contribute insights from Beam's development to open-source AI tools, sharing lessons learned during the model's creation.
Read more
Nvidia shifts from selling chips to selling AI infrastructure as a complete system
At GTC Berlin, Jensen Huang repositioned Nvidia's strategy away from graphics processors toward end-to-end AI deployment, introducing containerized factories, agent security frameworks, and structured data models that address enterprise bottlenecks beyond raw computing power.
Five Technology Shifts Will Push CIOs From Passive Oversight to Active Design
Enterprise leaders must architect AI systems proactively rather than react to rapid technological change, according to Gartner research presented at its IT Symposium/Xpo in Orlando.
Comet Cloud eyes underserved SMBs as GPU inference demand shifts
With AI workloads moving from training to inference, neocloud providers see opportunity in small and midsize businesses that hyperscalers have deprioritized. Comet Cloud is positioning itself to serve that market with dedicated clusters and aggressive pricing.