Reflection AI Unveils Beam, a 501B-Parameter Open-Source Model Trained on SpaceX Infrastructure
The startup, valued at $25 billion, has released Beam, an open-source large language model that matches the performance of much larger competitors while requiring significantly less computational power.
Reflection AI Inc. has unveiled Beam, an open-source large language model containing 501 billion parameters. The announcement arrives several months following the company's funding round at a $25 billion valuation, and coincides with reports that Reflection AI secured a $6.3 billion agreement with SpaceX Corp. to access Nvidia GB300 NVL72 systems for model training. Each of these appliances houses 72 graphics cards.
When tested against GLM-5.2, an open-source language model featuring approximately 250 billion additional parameters, Beam demonstrated superior performance on certain benchmarks while consuming between one-third and one-quarter of the computational resources. The company also claims Beam achieves performance levels comparable to Qwen 3.8-Max, which contains more than 2 trillion parameters.
The release carries significance given that many leading open-source language models originate from Chinese firms, including both Qwen 3.8-Max and GLM-5.2. Beam represents the first open-source model from a U.S. startup to achieve equivalent or superior performance metrics. Nevertheless, open-source models like Beam continue to lag behind frontier offerings such as Anthropic PBC's Claude Fable 5.1.
Training Process and Architecture
Reflection AI pursued an iterative development strategy for Beam, beginning with a modest prototype and progressively scaling to larger, more sophisticated versions. This progression culminated in Beam Base, the foundational model underlying Beam.
The company constructed Beam Base using a cluster comprising 6,144 graphics cards. Training involved 23.8 trillion tokens drawn from publicly available web content and commercial datasets. Reflection AI notes that the training corpus contained substantial quantities of programming code, with custom filtering mechanisms applied per language to eliminate substandard material.
Beam Base development completed in under four weeks. Following this phase, Reflection AI executed midtraining, a refinement procedure that expanded the model's context window and strengthened its reasoning abilities, preparing the groundwork for the subsequent, most computationally demanding training stage.
During the final phase, Reflection AI deployed 10,000 GB300 graphics cards and instantiated 1.3 billion reinforcement learning sandboxes—simulated environments where the AI model acquires new capabilities. These sandboxes were configured specifically for activities including code generation, web searching and AI agent operation.
The reinforcement learning phase also required four weeks. Reflection AI minimized delays through custom software designed to prevent training interruptions caused by system failures. The company reports that its infrastructure achieved a median recovery time of eight minutes across the 71 errors encountered during training.
Availability
Beam is currently accessible through an early access program. Reflection AI intends to distribute model weights, technical documentation and fine-tuning utilities before the month concludes.
Read more
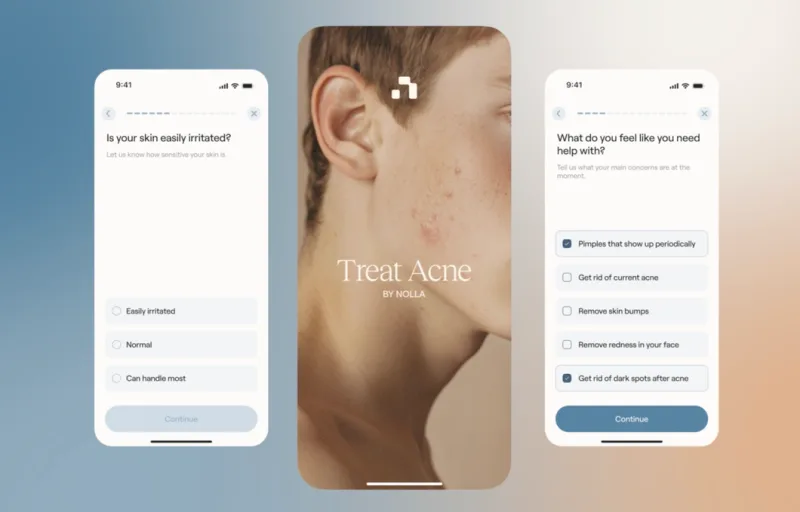
Utah Clears First AI-Powered Prescription System for Acne, Minimal Doctor Oversight
Nolla Health has won regulatory approval to operate an artificial intelligence system that can issue prescription refills for acne treatment with limited human physician review, marking the first such authorization in the United States.
Infor bets industry expertise can make AI agents trustworthy in enterprise operations
As agentic AI moves from labs into production systems, enterprises face a critical challenge: determining what autonomous systems should be permitted to do. Infor is positioning industry-specific context as the answer.
19-Year-Old Founder Raises $11M for Ghost, Launching $3,499 Personal AI Computer
Zain Javaid, who abandoned a career in quantitative finance after ChatGPT's release, has secured seed funding for Ghost, a startup building dedicated hardware for running AI agents locally on a person's device.