Photonics and Shared Memory Pools Target AI's Data Movement Bottleneck
As AI inference workloads strain data center efficiency, memory bottlenecks are becoming a critical cost driver. Marvell and Penguin Solutions are deploying photonic interconnects and shared memory pools to reduce the energy waste from moving data between GPUs.
Data movement has emerged as a significant efficiency challenge in AI infrastructure, particularly as inference workloads have begun to dominate training. GPUs frequently remain underutilized while waiting for data to arrive, and high-bandwidth memory, or HBM, remains physically attached to individual processors with no ability to be shared across systems.
Photonic interconnects represent a potential solution to these constraints. Marvell Technology Inc. has been combining optical technology with photonic memory capabilities to extend memory access beyond the physical boundaries of a single chip. According to Preet Virk, senior vice president and general manager of the Photonic Fabric Business Unit at Marvell, this approach delivers tangible improvements in the efficiency of data centers that organizations have already invested in.
In the data center today, we have a lot of room for improvement of efficiency. And when I say efficiency, I'm alluding to the wasted flops because we have GPU utilization that's very low.
Preet Virk, Marvell Technology
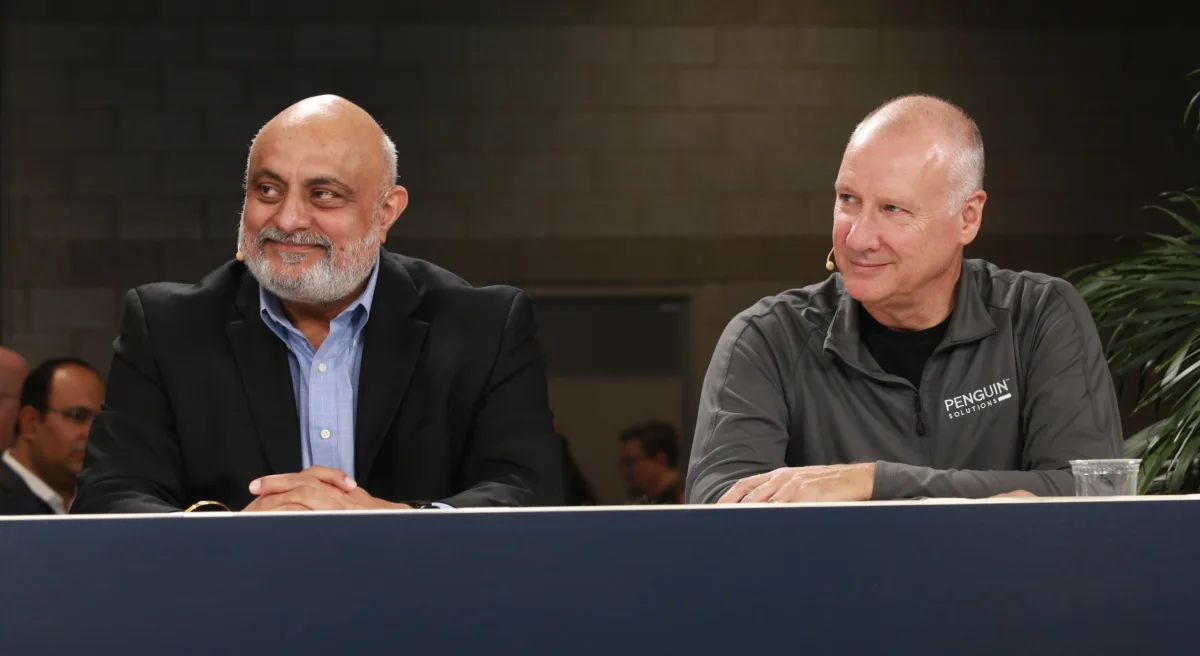
Virk and Andy Mills, vice president of advanced product development at Penguin Solutions Inc., discussed these challenges during SC26 in an exclusive conversation with theCUBE Research's John Furrier and Amit Eyal Govrin, broadcast on theCUBE, SiliconANGLE Media's livestreaming platform. Their discussion centered on how photonic technology and pooled memory architectures can address the memory constraints limiting AI infrastructure performance.
Shared pools take aim at memory bottlenecks
Penguin's MemoryAI Photonic Appliance relocates HBM into a standalone unit positioned tens of meters away from GPU clusters, with connectivity provided by Marvell's Photonic Fabric. Each appliance houses 16 terabytes of combined HBM and DDR5 memory that can be accessed by servers distributed across multiple racks.
The challenge there is making sure your LLM doesn't forget what you started talking to it about 10 minutes ago. To do that, you need a large amount of memory, large token lengths.
Andy Mills, Penguin Solutions
The energy implications of this architecture shift are substantial. Copper-based connections remain suitable for intra-rack communication, but connecting across larger clusters of thousands of GPUs necessitates optical pathways, according to Virk. He noted that memory transactions account for more than 80 percent of network traffic in large-scale deployments, and consolidating memory into shared pools eliminates much of this data movement entirely.
Within data movement, the memory transactions are a place to focus on. So with this solution versus a copper-based data movement, we could immediately get to a quarter of the energy, picojoules per bit, of data movement.
Preet Virk, Marvell Technology
The emergence of AI agents has intensified these pressures, as these systems generate substantially higher volumes of token requests compared to human-driven interactions. As inference operations expand across additional racks and geographic sites, Mills views shared memory pools as an essential practical response to mounting memory constraints.
https://www.youtube.com/embed/g0TFbXUCiBY?start=1&feature=oembed
If anything, distributed encourages shared because you don't want to recompute. The whole thing about KV cache was a huge success because it stops recomputation of the same data. And when you can share that data on a broader base and wider across more racks, your efficiencies go up as well.
Andy Mills, Penguin Solutions
Read more
Anthropic Researcher Claims Claude Proved the Riemann Hypothesis
Levent Alpöge, a researcher at Anthropic, announced he used Claude to prove one of mathematics' most significant unsolved problems, though the company has not officially confirmed the breakthrough.
Beyond Token Prices: Why Enterprise AI Cost Accounting Demands a Deeper Look
Companies pursuing multi-model AI strategies are discovering that token pricing alone masks the true cost of AI deployment. New data shows task efficiency and user consumption patterns drive the real bill.
Anthropic's IPO Surge Masks Broader AI Market Jitters as OpenAI Waits in the Wings
Anthropic's initial public offering delivered a solid 17% first-day gain, but the move may have signaled caution rather than momentum across the AI sector, with broader market concerns weighing on technology stocks.