AI agents force Kubernetes to rethink resource management as workloads defy traditional scaling
Autonomous orchestration is emerging as the answer to erratic AI agent behavior, which crashes 80% more often than traditional microservices and leaves static resource allocation either wasteful or insufficient.
The rise of AI agents is upending how platform teams manage cloud infrastructure, with autonomous orchestration stepping in to handle workload patterns that defy conventional planning. Agent-based systems alternate between idle periods and sudden resource demands, a rhythm that renders fixed resource allocation either inefficient or prone to failure.
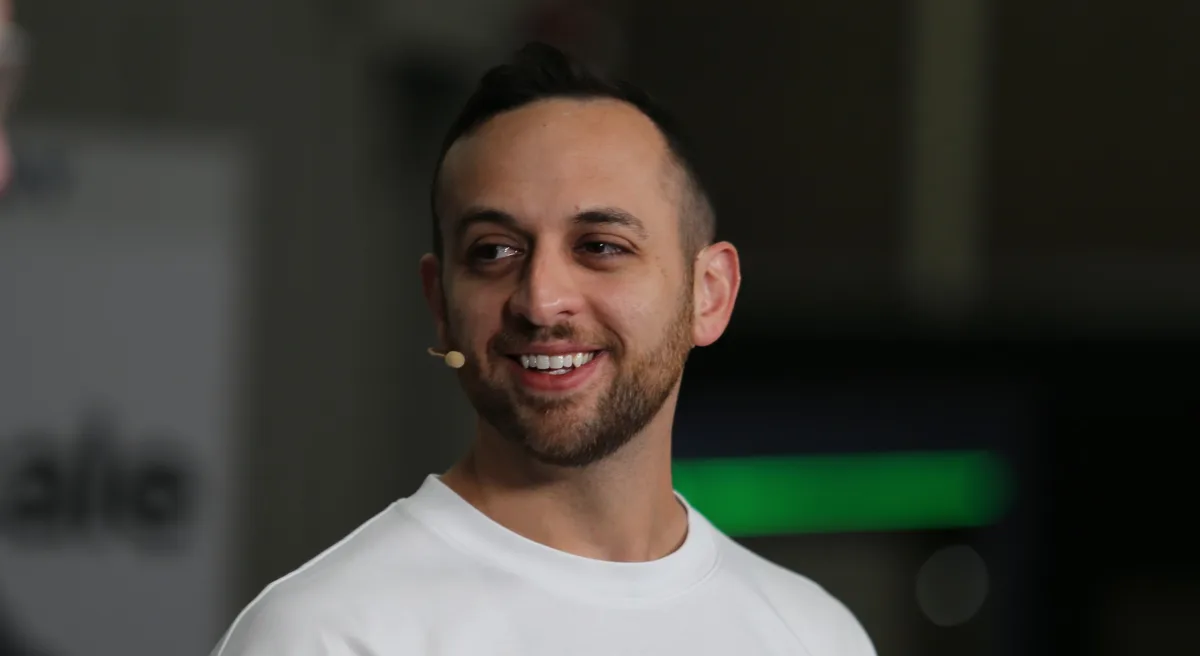
Kubernetes has become central to production AI deployments, but agents are introducing fresh operational challenges. Infrastructure expenses are climbing, and reliability issues are harder to prevent because agents ultimately consume CPU and memory for every action they take, according to Yodar Shafrir, founder and chief executive officer of ScaleOps Inc.
Agents and all the agent workloads pretty much made everything way more complex when managing infrastructure. Eventually, all the complexity that existed before just got much worse. Today, the compute cost has grown dramatically. Everything that agents execute eventually runs on compute.
Yodar Shafrir, ScaleOps
Shafrir discussed these challenges during an exclusive broadcast at KubeCon + CloudNativeCon NA with theCUBE Research's Paul Nashawaty and Rebecca Knight, exploring how real-time resource adjustment through autonomous orchestration can reduce both expenses and system failures.
Why autonomous orchestration fits the agentic era
Agent behavior diverges significantly from how traditional microservices operate. An agent typically waits for input from a human or another agent, queries a large language model, and then executes its assigned task in a rapid burst. This pattern forces teams to reserve resources for peak demand while the agent maintains its memory state throughout. When resource constraints are hit, a failed step must restart and consumes tokens again in the process.
We actually see that agents crash due to not having enough resources 80% more often compared with traditional microservices. The reliability is much harder to manage.
Yodar Shafrir, ScaleOps
ScaleOps addresses this challenge by making resource decisions dynamically as conditions change. The platform adjusts allocations, replicas and node placement for each application, agent and Model Context Protocol server, claiming reductions in cloud costs between 70% and 80%. Companies including Adobe Inc. and Salesforce Inc. have adopted the approach, often beginning with read-only deployments on their most critical systems to build confidence.
We understand for every application: What is it connected to? What does it communicate with? What is the business state of every application? We learn from historical patterns.
Yodar Shafrir, ScaleOps
ScaleOps has introduced additional features to optimize agent resource usage. The platform allows other workloads to access an agent's allocated resources during idle periods, and implements memory swap to grant agents memory only when needed. According to the company, these techniques achieve 90% greater cost efficiency for agent operations while keeping deployments within Kubernetes. Given the expense of continuously running agents, Shafrir views autonomous orchestration as the only viable approach.
https://www.youtube.com/embed/sZew7zgDgBs?feature=oembed
We are now in a phase where humans and all the traditional scaling capabilities that existed in the past are pretty much irrelevant for today's world because they're too static and they require a human to go and configure them. When things are so dynamic, it no longer works the same way.
Yodar Shafrir, ScaleOps
Read more
Anthropic Researcher Claims Claude Proved the Riemann Hypothesis
Levent Alpöge, a researcher at Anthropic, announced he used Claude to prove one of mathematics' most significant unsolved problems, though the company has not officially confirmed the breakthrough.
Beyond Token Prices: Why Enterprise AI Cost Accounting Demands a Deeper Look
Companies pursuing multi-model AI strategies are discovering that token pricing alone masks the true cost of AI deployment. New data shows task efficiency and user consumption patterns drive the real bill.
Anthropic's IPO Surge Masks Broader AI Market Jitters as OpenAI Waits in the Wings
Anthropic's initial public offering delivered a solid 17% first-day gain, but the move may have signaled caution rather than momentum across the AI sector, with broader market concerns weighing on technology stocks.